Section 3.4 Generative model architecture
Decoding, context and inference cost
At every step, the model turns the last position’s representation into scores, called logits, for the tokens in its vocabulary. Greedy decoding chooses the largest score. Sampling draws a token from a distribution. The selected token joins the input before the next step.
Temperature and probability mass
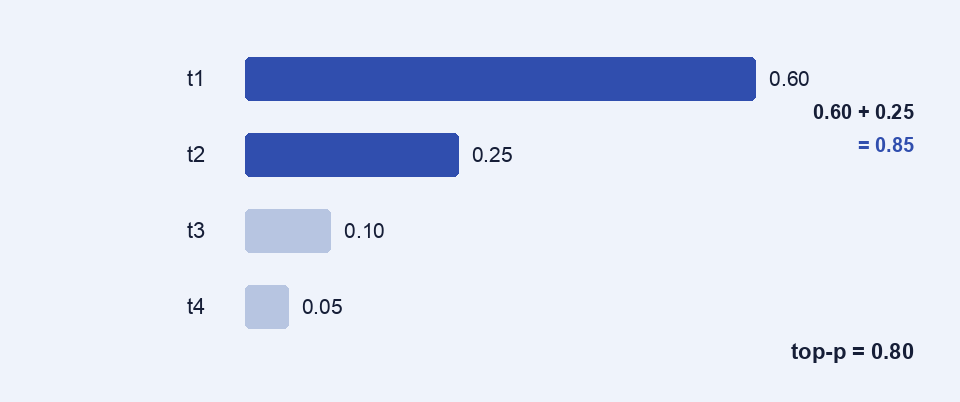
With strictly positive temperature T, divide the logits by T before softmax. A small value concentrates probability on the highest scores. Top-p sampling sorts tokens by probability and keeps the smallest prefix that reaches the chosen mass, then renormalizes. With probabilities 0.60, 0.25, 0.10 and 0.05, a cutoff of 0.80 keeps two options. Their new probabilities are approximately 0.706 and 0.294. This procedure changes output diversity. The probabilities describe text continuations and inherit the limitations of the underlying training.
Fit information into the context window
Instructions, conversation history, reference passages and the reply share finite capacity. Even when all the material fits, a model can overlook a crucial detail. Time to first token includes processing the input text. Sequential generation adds latency for each output token. A key-value cache keeps computations from previous positions so they are not repeated at every step, using additional memory. In a document task, dropping irrelevant passages can improve both cost and the visibility of the evidence.